Look Less, Think Faster: Joint Token-Compute Adaptation for Multimodal LLMs
Pengcheng Wang, Zhiquan Wang, Jayoung Lee, Zhuoyan Xu, Ran Xu, Saurabh Bagchi, Yin Li, Somali Chaterji (2026). Look Less, Think Faster: Joint Token-Compute Adaptation for Multimodal LLMs 2026.
Abstract
Multimodal Large Language Models (MLLMs) have recently demonstrated strong performance across
vision-language tasks. However, their high inference cost, arising from both the large number of input
visual tokens and the heavy computation of the large language model (LLM), remains a key barrier to
practical deployment. Recent work attempts to reduce the cost by adaptively optimizing individual
dimensions, e.g., pruning redundant visual tokens or skipping LLM layers and heads. Nonetheless, prior
approaches typically treat these dimensions independently and overlook a fundamental coupling: the
available compute resources must be dynamically allocated across all dimensions based on the input
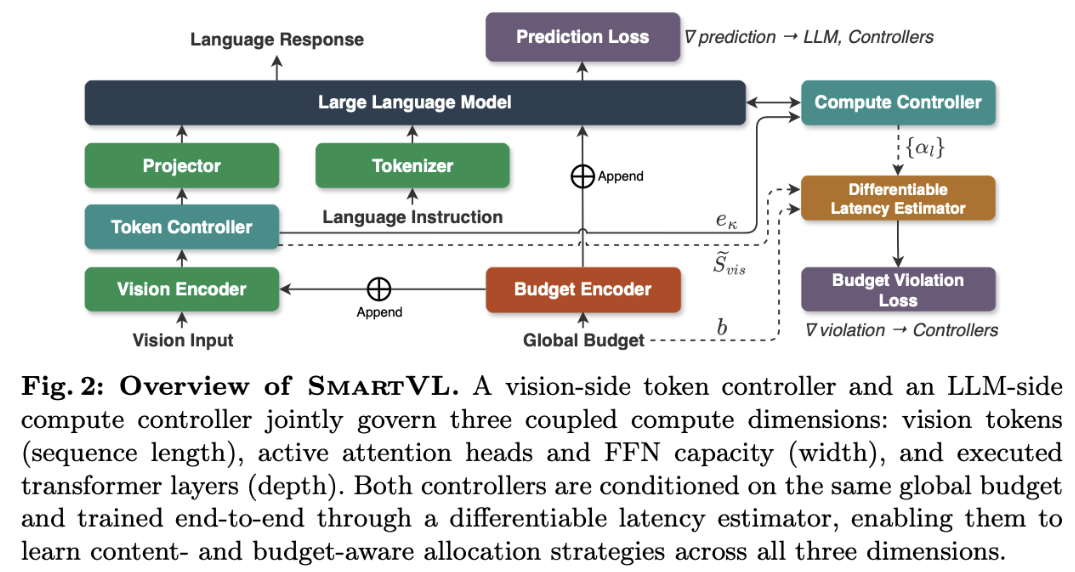
content. To bridge the gap, we propose SmartVL, a unified adaptive inference framework that jointly
controls vision token number and model compute capability in response to varying input contents and
compute budgets. SmartVL introduces a vision-side token controller that dynamically selects informative
visual tokens and an LLM-side compute controller that adaptively adjusts LLM computation. Importantly,
these controllers are trained to coordinate with each other so that the overall inference cost satisfies
a target budget. To allow this joint scheduling, we connect the controllers using a shared budget
encoding and leverage a differentiable latency estimator for end-to-end training. This design enables
SmartVL to learn cross-stage allocation strategies that adapt to both input complexity and runtime
compute constraints. Experiments across multiple MLLM benchmarks demonstrate that, with joint scheduling,
SmartVL consistently outperforms prior adaptive methods and achieves superior accuracy-efficiency Pareto
frontiers. Project page:
https://www.schaterji.io/publications/2026/jointtokencompute.